Why Industrial Data Integration Demands a Unified Namespace
For years, the factory floor and the IT department spoke different languages. SCADA systems pumped out time-series data from PLCs, while ERP systems demanded clean, structured records for planning. The result was a tangle of point-to-point connections, custom scripts, and ETL jobs that broke as soon as anything changed. I have seen teams spend months building a data pipeline from a single production line, only to redo it when a sensor model was swapped. That kind of friction is not just expensive. It stops digital transformation dead.
What the industry really needs is a way to treat data as a shared resource, not a project-by-project headache. That is where the idea of a Unified Namespace becomes practical. Instead of moving and copying data between silos, you create a live, central address space where every piece of information lives once and is available to any consumer that needs it. This is not a theoretical concept. It is the architectural shift that makes industrial data integration possible at scale.
The Old Way: Pipelines That Leak
Traditional industrial data integration relied on extracting data from one system, transforming it, and loading it into another. ETL tools worked well enough for batch reporting, but they could not keep up with the velocity and variety of modern manufacturing. A data lake might hold years of history, but getting a real-time view of a machine's vibration profile meant waiting for the next scheduled batch. By the time the data arrived, the insight was stale.
Worse, every new use case required a new pipeline. Want to feed vibration data into a machine learning model for predictive maintenance? Build another connector. Need to share quality metrics with the MES? Write another adapter. Over time, the integration landscape became a spiderweb of brittle connections. Each one had to be maintained, monitored, and updated whenever a source system changed. That is not scalable. It is a tax on every digital initiative.
Enter the Unified Namespace
A Unified Namespace flips the model. Instead of moving data between systems, you publish data once into a shared namespace that all systems can subscribe to. This is not a new database or a data lake. It is a real-time data fabric that sits between your industrial IoT devices, your edge computing nodes, and your enterprise applications. Every piece of data gets a unique address, and any authorized consumer can read it directly.
For this to work in an industrial environment, the namespace must support the protocols already in use. OPC UA has long been the standard for semantic interoperability on the factory floor. MQTT, especially with the Sparkplug specification, provides a lightweight pub/sub model that works well over unreliable networks. A good Unified Namespace implementation speaks both. It does not force you to rip out your existing SCADA or replace your PLCs. It wraps them in a common layer of meaning.
Real-Time Data Without the Lag
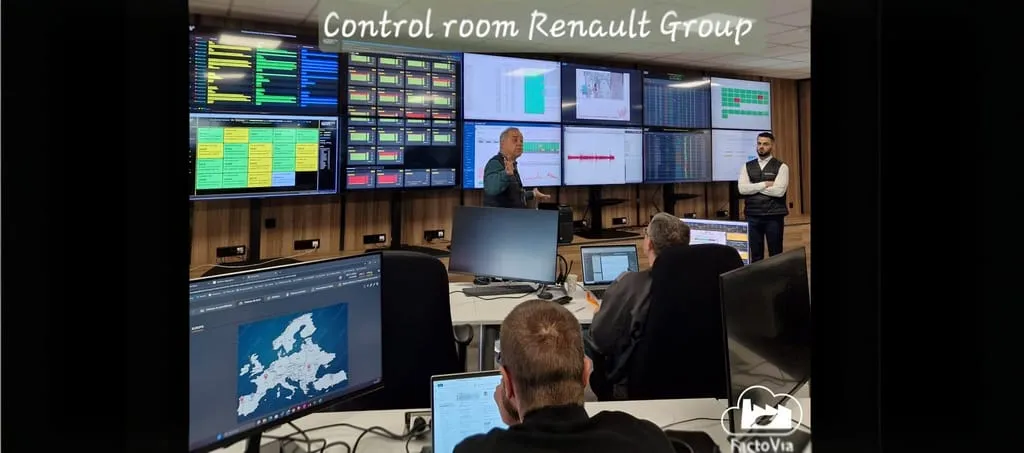
One of the first benefits you notice is speed. When a sensor on a packaging line detects a temperature spike, that value appears in the namespace within milliseconds. An edge computing node running a machine learning model picks it up instantly, compares it against historical time-series data, and triggers a warning before the product is damaged. No ETL job. No waiting for the next batch window. The data flows as events, not as files.
This immediacy changes what you can do with data governance. Rather than governing data after it lands in a warehouse, you govern it at the source. You define who can read what, how long data is retained, and what transformations are applied, all within the namespace itself. That makes compliance with internal policies and external regulations simpler, because the rules are attached to the data, not to the pipeline that moves it.
IT-OT Convergence Becomes Practical
The concept of IT-OT convergence has been discussed for years, but it rarely worked well in practice. The IT side wanted REST APIs and JSON payloads. The OT side wanted OPC UA and binary data. Each group had valid reasons, but bridging the two worlds usually meant building gateways that added latency and complexity. A Unified Namespace provides a neutral ground. It understands OPC UA information models and it can expose the same data as MQTT topics with Sparkplug tags. Both sides get what they need without hacking together custom translators.
This is where industrial data integration shows its real value. When you can connect a historian, a machine learning pipeline, and a cloud analytics platform to the same namespace, you stop treating integration as a separate project. It becomes a byproduct of how you architect your data. The term "industrial data integration" then describes not a one-time effort but a continuous capability.
From Data Mesh to Smart Manufacturing
The data mesh is another architectural pattern that complements a Unified Namespace. In a data mesh, domain teams own their data and expose it through standardized interfaces. The namespace acts as the discovery and access layer. Anyone in the organization can find and use the data they need without copying it into a central lake. This reduces duplication and keeps data fresh.
In smart manufacturing, this matters because production data is inherently distributed. Each cell, each line, each plant generates its own time-series data. A data mesh organized around a Unified Namespace lets you query across all of them as if they were one system. Want to compare cycle times from three factories? The data is already there, addressable and consistent. You do not need to move it first.
Machine Learning Needs Clean, Live Data
Machine learning models are hungry for data, but they are also sensitive to quality. A model trained on batch-processed logs may fail when fed raw, noisy sensor streams. A Unified Namespace helps here by providing a single source of truth that includes metadata about data quality, calibration status, and unit of measure. The model can read not just the value but also its context. That reduces the time spent on data wrangling and increases the chance that predictions are reliable.
For example, a model predicting bearing wear on a conveyor motor needs vibration amplitude, temperature, and run time. In a traditional setup, those signals might live in three different systems with three different timestamps. In a Unified Namespace, they are all published to the same logical address space with synchronized timing. The model subscribes to the relevant topics and gets a coherent picture in real time.
Practical Trade-Offs and Judgment Calls
Adopting a Unified Namespace is not without cost. It requires an upfront investment in defining the namespace structure, mapping existing data sources, and training teams. The protocols themselves have limitations. MQTT, even with Sparkplug, does not guarantee exactly-once delivery in all network conditions. OPC UA can be heavy for very constrained edge devices. You have to decide where to apply each protocol and how to handle edge cases like network partitions or device failures.
Data governance also becomes more nuanced. When every system can read everything, you need fine-grained access control. Not every operator needs to see the maintenance schedule for a robot. Not every enterprise application should write setpoints back to a PLC. A good namespace implementation supports role-based access and audit trails, but you have to configure them deliberately. That takes time and discipline.
Another trade-off is between centralization and autonomy. A namespace that is too rigid will frustrate domain experts who need to add new data types quickly. One that is too loose will become chaotic. The right balance is to define a core set of standard objects and allow extensions within each domain. The OPC UA companion specifications provide a good starting point, especially for common equipment types like motors, pumps, and conveyors.
What This Means for Industry 4.0
Industry 4.0 initiatives often stall because the data foundation is not solid. Companies invest in sensors, edge devices, and analytics platforms, but they overlook the plumbing that connects them. A Unified Namespace is that plumbing. It turns a collection of smart devices into a coherent system. It makes Enterprise Data Management a live, operational concern rather than a back-office function.
The phrase "industrial data integration" used to evoke images of complex middleware and armies of consultants. With a Unified Namespace, it becomes more about design and less about brute force. You design how data is named, organized, and accessed, and the integration follows naturally. That is a shift I have seen succeed in plants that were previously stuck in point-to-point hell. It is not magic. It is just a better architecture.
If your organization is planning a digital transformation, consider starting with the data layer. Ask how you will name things, how you will make them discoverable, and how you will ensure they stay current. The answers to those questions will determine whether your Industry 4.0 projects deliver lasting value or become another set of silos. A Unified Namespace is not the only answer, but it is the one that makes the rest of the stack work.
